ぜひ弊社まで サーバーシャーシ エンジニアおよび営業チーム
チャンネル登録者数24,000人
お客様の用途、シャーシの種類、ラックの高さ、マザーボード、GPU、ドライブベイ、電源、冷却システム、I/O、および注文数量をお知らせください。当社のエンジニアおよび営業チームが、お客様のプロジェクトに適した標準モデルまたはOEM/ODM構成をご提案いたします。.
チャンネル登録者数24,000人
お客様の用途、シャーシの種類、ラックの高さ、マザーボード、GPU、ドライブベイ、電源、冷却システム、I/O、および注文数量をお知らせください。当社のエンジニアおよび営業チームが、お客様のプロジェクトに適した標準モデルまたはOEM/ODM構成をご提案いたします。.
A GPU server case, also called a GPU server chassis, is a rack-ready enclosure designed to integrate graphics processing units with the CPU, motherboard, storage, networking, cooling, and power components. It provides the GPU density, airflow, power delivery, expansion, and workload-specific setup required for reliable accelerated compute.
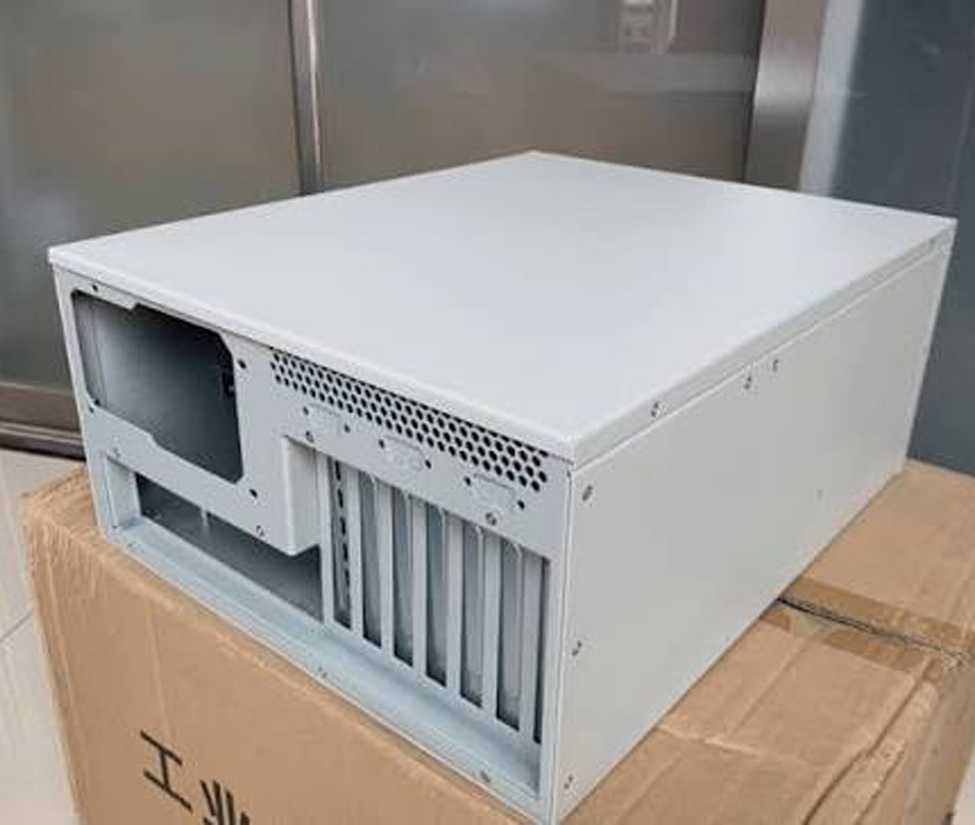
It is a specialized enclosure for building a system around demanding graphics, simulation, accelerated computing, or high-performance computing tasks. Unlike a standard computer case or general-purpose rackmount server case, it must account for substantial airflow, physical clearance, carefully spaced PCIe connections, stable power distribution, and mechanical support for large accelerator cards.
The chassis coordinates GPU dimensions, CPU platform, board layout, expansion architecture, fan wall, power supplies, storage bays, and network adapters. The enclosure is part of the system design, not simply a metal shell.
The right form factor balances rack density with cooling capacity, serviceability, expansion, and application needs. A 1U or 2U chassis suits compact deployments; a 4U or 5U design provides more room for full-height cards, airflow, storage, and cabling; an 8U or larger platform supports dense accelerators, high-capacity cooling, redundant power, and infrastructure-scale servicing.
Actual GPU capacity is never determined by height alone. It depends on the internal layout, GPU length and slot width, board design, riser topology, thermal system, power supplies, and expansion-slot placement.
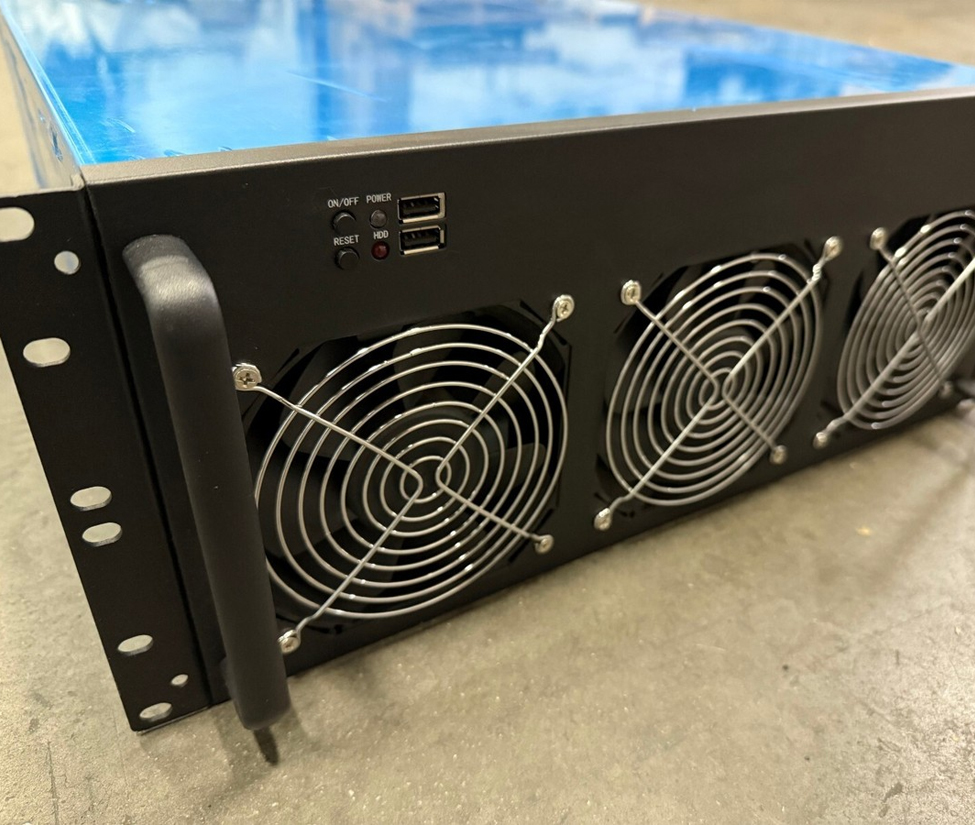
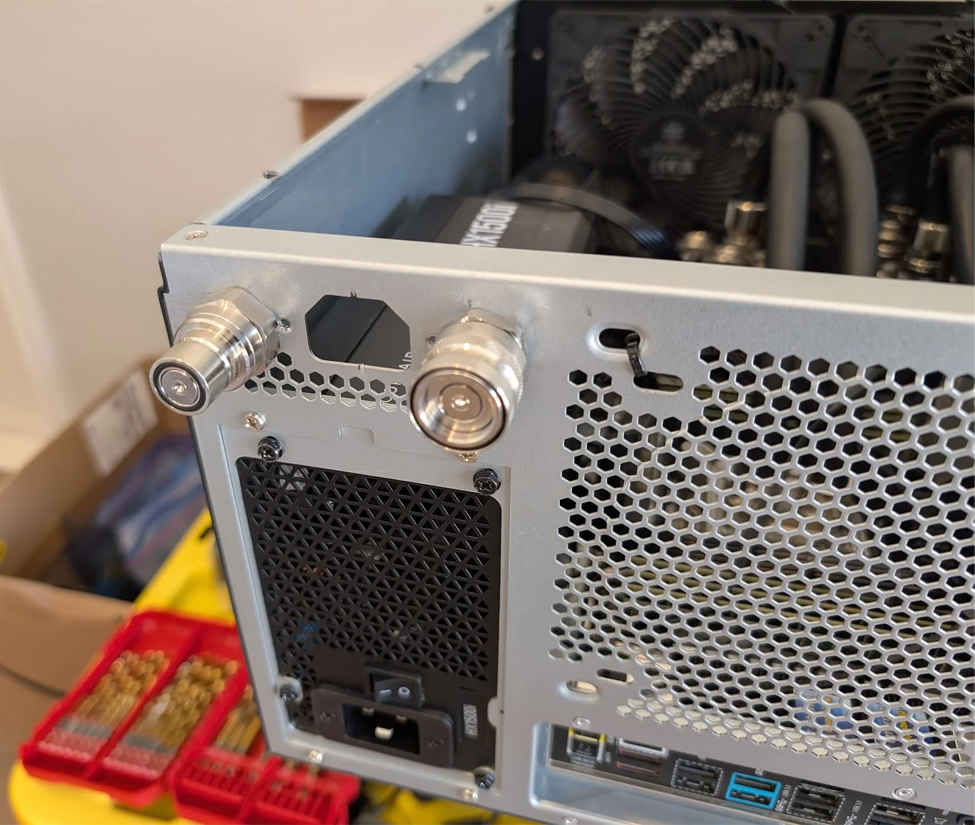
1U and 2U GPU servers commonly fit workloads where rack density and efficient deployment matter more than the highest possible number of full-size GPUs. Typical applications include:
A compact GPU server can place accelerated processing close to users, cameras, or machines while preserving server rack capacity. Final sizing still depends on GPU dimensions, cooling mode, storage, and the available power environment.
A 4U chassis is widely used for high-performance multi-GPU systems because it offers practical space for accelerators, fans, PCIe routing, storage, and service access. Common 4U applications include AI training, LLM and generative AI development, deep learning, 3D rendering, animation, architectural visualization, scientific simulations, financial modeling, big data processing, and mainstream HPC.
Some properly designed 4U platforms can accommodate up to eight full-sized GPUs, depending on the platform, cooling design, board layout, and GPU type. Current 4U rackmount server designs show the range between direct-connect cards and HGX-class baseboards.
A 4U case is not automatically suitable for every graphics card. Fan pressure, inlet temperature, card spacing, power cabling, cable paths, and active or passive cooling must all be validated.
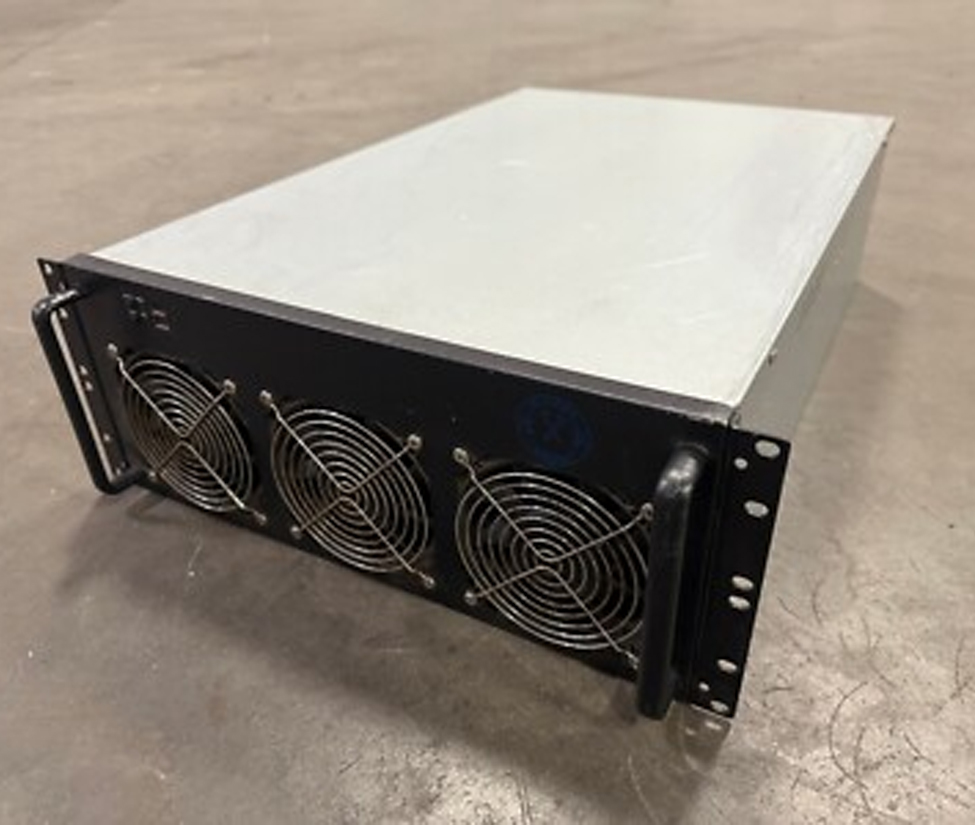
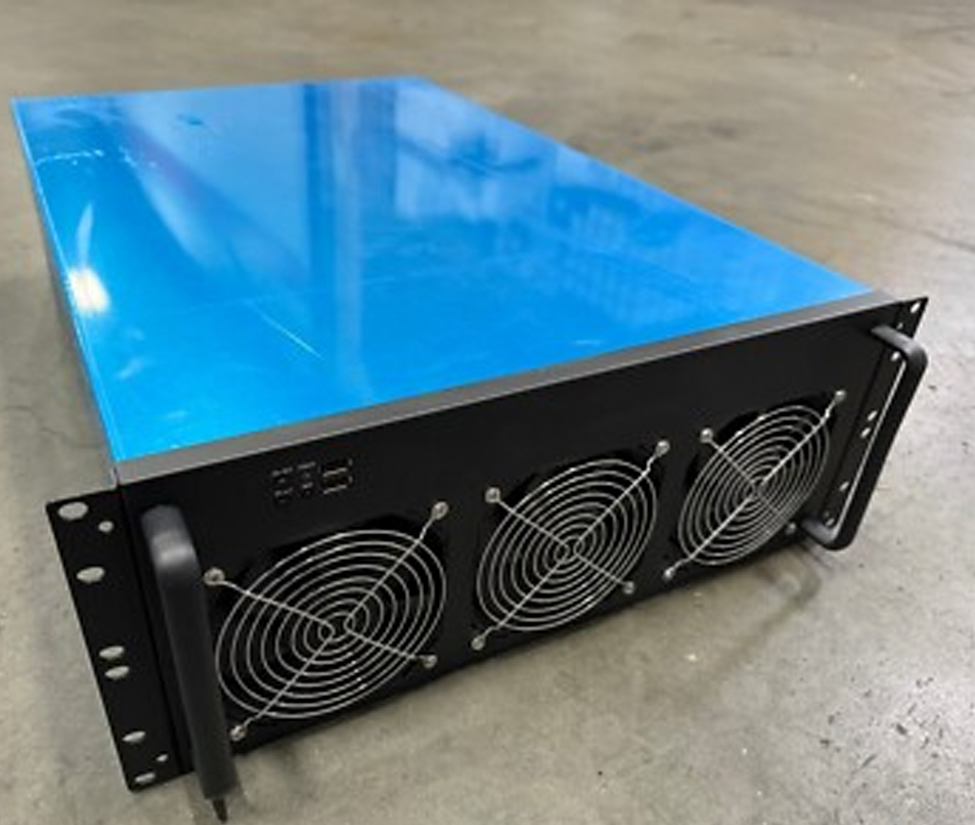
8U and larger GPU systems make sense when accelerator density, cooling capacity, redundancy, GPU-to-GPU connectivity, and serviceability outweigh rack-space efficiency. Enterprises, universities, research institutions, national laboratories, data center operators, and AI infrastructure providers use these platforms for generative AI clusters, foundational-model development, enterprise supercomputing, scientific computing, multi-node GPU infrastructure, high-density enterprise accelerators, and other demanding deployments.
HGX-class platforms combine multiple GPUs with high-speed interconnects for scale-up AI and accelerated computing workloads. Larger systems also provide space for cooling hardware, networking, storage, and a redundant power supply; commercial 8U platforms demonstrate integration with extensive expansion and multiple 2.5-inch drive bays.
For buyers comparing GPU servers for AI, these relationships are useful starting points rather than universal limits:
| 申し込み | Common Chassis Size | Primary Design Priority |
|---|---|---|
| VDI, cloud gaming, remote graphics | 1U or 2U | Rack density and efficient deployment |
| Edge inference, video analytics, sensor processing | 1U or 2U | Local compute, airflow, compact integration |
| AI model training, rendering, mainstream high performance computing | 4U | Multi-GPU capacity, cooling, expansion |
| Large generative AI clusters, supercomputing | 8U or larger | Accelerator density, interconnects, redundancy |
Evaluate the chassis as part of the complete GPU system. Confirm these factors before purchase:
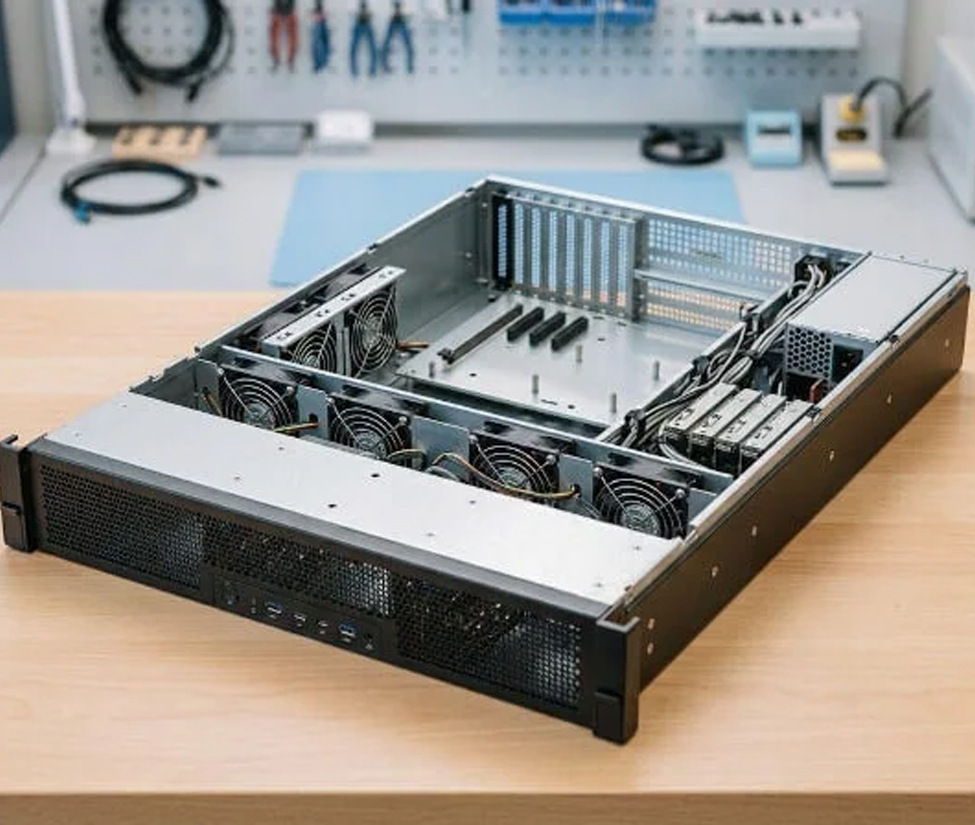
A GPU server case houses one or more GPUs together with the CPU, motherboard, storage, networking, cooling, and power components required for accelerated workloads. Compared with a general-purpose server enclosure, it is designed around GPU clearance, concentrated heat output, PCIe connectivity, power distribution, and service access. Typical applications include AI training, AI inference, rendering, virtual workstations, video analytics, scientific computing, and HPC.
Choose the form factor according to the workload, GPU dimensions, cooling requirements, expansion needs, and available rack space. A 1U or 2U chassis is commonly used for compact inference, VDI, video analytics, or remote graphics deployments. A 4U platform is often selected for multi-GPU AI training, rendering, and mainstream HPC, while 8U and larger systems are generally considered for dense accelerator platforms and infrastructure-scale AI clusters. These are guidelines rather than fixed limits; current server portfolios include 4U, 5U, 8U, and 10U designs for different AI and HPC architectures.
Some 4U systems support up to eight GPUs, but this capability depends on the specific platform, GPU type, PCIe topology, motherboard layout, thermal design, and power system. For example, current Supermicro 4U platforms include configurations designed for up to eight direct-connect PCIe GPUs, but that specification should not be applied to every 4U chassis. Always verify the complete system configuration rather than relying on rack height alone.
Confirm the GPU length, height, slot width, cooling method, and power requirements first. Then review PCIe generation and lane allocation, riser design, CPU and motherboard compatibility, fan capacity, airflow direction, power connectors, redundant power options, storage bays, rack depth, cable routing, and maintenance access. Manufacturer qualification is especially useful because it evaluates thermal, mechanical, power, and signal-integrity requirements together.
An HGX-class platform is more appropriate when the workload requires a tightly integrated multi-GPU architecture, high-speed GPU-to-GPU communication, enterprise networking, and scale-up AI or HPC capability. NVIDIA describes HGX as a platform combining GPUs, NVLink, networking, and optimized software, so it differs from a conventional chassis populated with independent PCIe graphics cards. The correct choice depends on model size, communication patterns, cluster design, cooling infrastructure, power availability, and budget.
The right chassis protects the value of the entire GPU server by aligning accelerator fit, connectivity, cooling, power, storage, and service access with the intended application.
Share your preferred GPUs, GPU quantity, motherboard model, CPU platform, storage requirements, rack-space limits, cooling requirements, power environment, and intended AI, rendering, inference, or high-performance compute workload.


